
Fouad Wahabi
Software Engineering Lead

Alex Barksdale
Senior Software Engineer

Kai Xin Tai
Senior Product Manager

Uday Tennety
Head of Technology Partnerships
Teams that build agents on open models hosted on Fireworks AI, such as GPT-OSS, Kimi, GLM, Qwen, and MiniMax, need a reliable way to measure whether their LLM applications and agents are giving accurate, safe, and helpful answers efficiently. Datadog Agent Observability now supports Fireworks AI as a model provider, so you can get end-to-end visibility into your agents built on Fireworks AI, from traces and token usage to quality evaluations. You can bring your own Fireworks AI API key and use models hosted on Fireworks AI to power LLM-as-a-judge evaluations and to experiment in the Agent Observability Playground.
In this post, we’ll show you how Datadog’s Fireworks AI integration lets you run LLM-as-a-judge evaluations with Fireworks AI models and experiment with those models in the Agent Observability Playground. You can test prompts against Fireworks AI models in the Playground, then review the results alongside the rest of your Agent Observability data.
Run LLM-as-a-judge evaluations with Fireworks AI models
After you connect your Fireworks AI account once, every model it can access is available anywhere Agent Observability lets you choose a model provider. LLM-as-a-judge evaluators use a model to score the inputs and outputs of your LLM application, so you can catch issues such as hallucinations, off-topic answers, or negative user sentiment at scale.
With Fireworks AI models as your judge, you can match the model to the job: a larger model such as gpt-oss-120b for nuanced quality checks, a low-latency router endpoint for high-volume scoring, or your own fine-tuned model for domain-specific criteria. Because evaluations run on your Fireworks AI account, model usage follows the billing and governance controls you’ve set up, and you choose the trade-off between cost and quality for each evaluator. You also don’t need to build a separate pipeline to export traces, call a model, and write scores back.
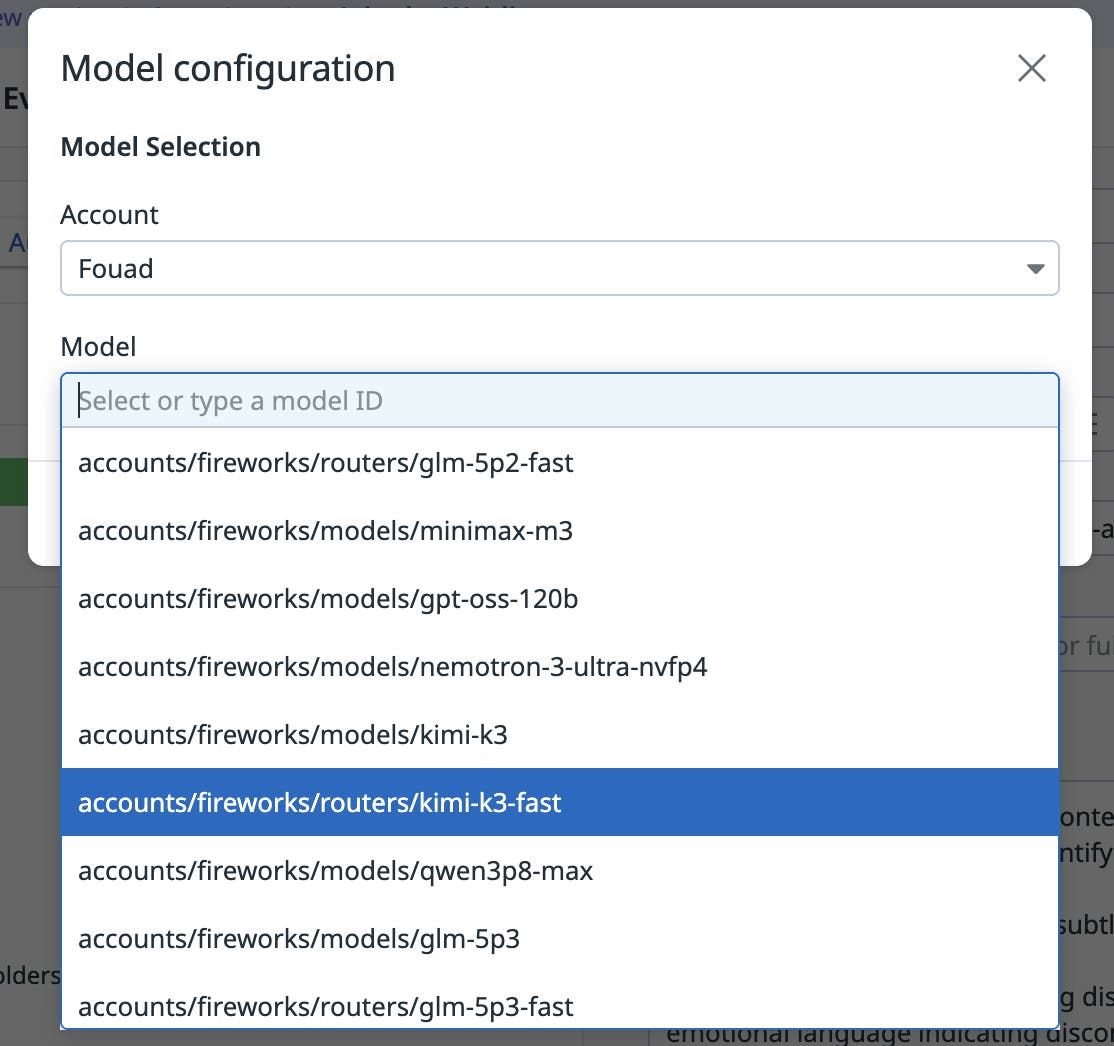
Datadog then runs the evaluator against your production traces using the selected Fireworks AI model, scoring your LLM traces for qualities like faithfulness, topic relevance, or sentiment alongside the rest of your observability data. Results appear next to each span, and you can track them over time, filter traces by score, and alert on regressions.
Experiment with Fireworks AI models in the Playground
Datadog’s Agent Observability Playground lets you iterate on prompts before they reach production. For example, if you run a support assistant for an online travel agency, you may want to know whether an open model can answer refund and cancellation questions accurately and whether it’s fast enough for a live chat. In the Playground, you can run your system prompt and a real customer question against gpt-oss-120b and immediately see the response alongside its token count and latency.
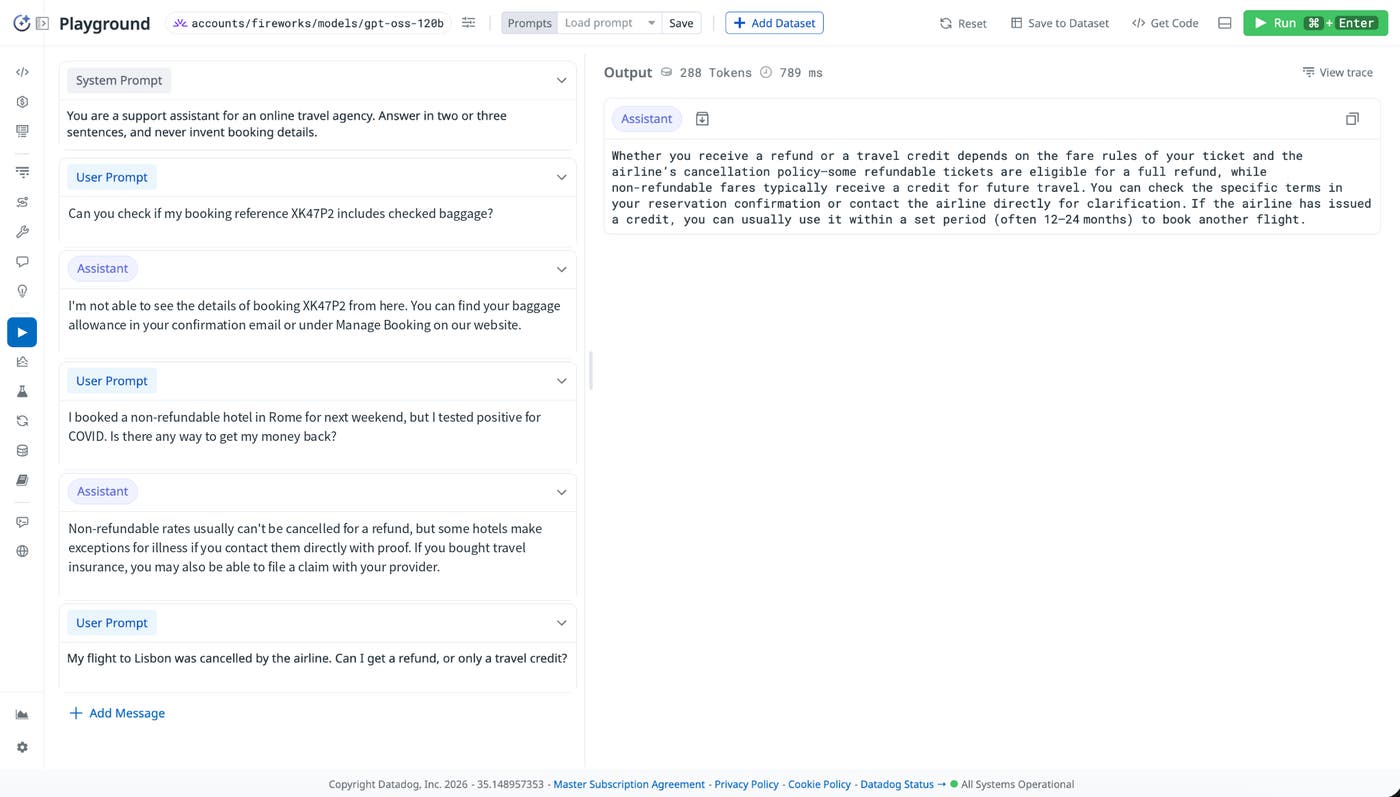
From there, you can swap in other Fireworks AI models, including low-latency router endpoints like Nexus Auto, to weigh answer quality against speed and cost. You can also open the full trace for any run to see exactly what the model received and returned. When a prompt looks promising, run it against a dataset of real customer questions to help ensure it holds up beyond a single example. Once you have a model and prompt you trust, select “Get Code” to copy the configuration into your application. The same Fireworks AI models can power the evaluators that monitor it in production.
Get started with Fireworks AI and Datadog
The Fireworks AI integration is available today for all Datadog Agent Observability customers. To connect your account and learn more about evaluations and Playground, see the Fireworks AI integration documentation.
If you’re new to Datadog, you can get started with a 14-day free trial. New to Fireworks AI? Sign up for an account to get an API key.
